Examples¶
Sixteen working applications ship in examples/ (in-repo, not packaged). They
are the reference implementations for the recipes,
patterns and the port matrix — canonical
examples are split into a produce/ package (stages) + thin
web.py/chat.py/main.py entries.
All demos run with or without API keys: configure .env (copy
.env.example) for LLM/embedder/image providers, or let them fall back to
deterministic demo mode.
The session-chat demos (knowledge, devops, research, repair) build
their web layer on the canonical reactifact.chat + reactifact.web contract —
each supplies only the domain hooks (agents, input model, terminal reply),
the SSE transport and session persistence come from the framework. Ports
(reflection …) and adaptive are CLI-only by design.
Tutorial ladder¶
llm_ladder— the recommended starting point: the LLM workflow from a single call (level 1) through patching artifacts (level 2) to a full state-changing session with lifecycle (level 3). Self-contained, offline fallbacks, model mode via.env. See index.
starter_app — a copy-pasteable web app over the quick cases¶
What it shows: one FastAPI process you can clone and run, covering the
shapes most apps start with — a structured call, RAG with citations, an LLM with
tools, and a session-persisted chat — plus a trace dashboard for all of them.
It's a thin skin over reactifact.quick,
and the provider is chosen by from_env(): no key → offline/deterministic
fallbacks (RAG still answers from knowledge/ with citations); OPENROUTER_API_KEY
→ OpenRouter; OPENAI_BASE_URL → any OpenAI-compatible endpoint. Copy the
directory and swap the domain.
knowledge — multi-source chat with evidence¶
What it shows: fan_out_sources search over file + CSV sources → lazy
materialize_doc → evidence extraction → claim verification → answer with
provenance; deterministic CSV calculation (Spreadsheet → Calculation).
uv run python ./examples/knowledge/web.py    # FastAPI/SSE + trace dashboard
uv run python ./examples/knowledge/chat.py   # interactive CLI
Key files: produce/ (common, router, search, evidence, calc, lifecycle),
agents.py, web.py.
research — goes to the web¶
What it shows: WebSource with real URL discovery; lazy page resolution
only for pages the model ranks relevant (§6); evidence → verified claims →
answer with URL provenance; StatusMachine turn lifecycle.
medic-lab — hypothesis laboratory¶
What it shows: one question spawns competing hypotheses; each is
investigated over an evidence pool; scored by support/contradiction counts
(scores are calculated, not guessed); HITL steering via PendingQuestion;
honest report when evidence is insufficient; concurrency_limit (LLM agents = 2,
global cap = 6).
devops — HITL tool agent (ops assistant)¶
What it shows: HITLLMAgent + LLM tool router (routing is a separate
structured step, StructuredLLM), HITL-approved mutations for Kubernetes,
GitLab, Ansible (each is a fateful operation the LLM cannot dream up on its
own); trace dashboard with the create_trace_router UI.
incident_commander — a full harness, composed¶
What it shows: every harness-level building block wired together in one
scenario instead of five separate toy demos — branch & merge
(Context.branch()/merge(), §39-§40), each relevant place investigated
independently on its own fork — relevant decided by a deterministic
keyword classifier, not "always fork everything" — sub-agent delegation
(agent_tool.AgentAsTool, a DBA specialist consulted on the database fork),
a token-bounded rolling synthesis
(context_builder.TokenBudgetContextBuilder), a destructive-tool approval
gate (tool_use.ToolUseHITL, the actual fix pauses for a yes/no), and
inline verification before the incident is considered resolved
(verify.Verify, provenance_grounded required). Runs fully offline via a
scripted provider (ToolUseHITL's decision loop has no offline fallback of
its own) or with a real key.
uv run python -m examples.incident_commander.main
uv run python -m examples.incident_commander.main --context-max-tokens 30
repair — budget-aware replanning (Russian by design)¶
What it shows: chat and catalog data are intentionally Russian — the
contrast with other English examples is deliberate (localization is a product
concern, not a framework one). The flow: fact collection → LLM design options →
3 photo previews → plan → deterministic catalog estimate → HITL approval →
budget complaint triggers a rebuild from an earlier stage with a _downstream_resets
rollback. Everything explicit is deterministic; only genuinely generative steps
use the LLM.
forklab — branch & merge (§39-§40)¶
What it shows: deterministic alternative-state exploration — one question,
two research strategies on their own forks (Context.branch()); a
three-way merge() that either unions cleanly or raises an explicit
MergeConflict (§40, never a silent choice); an evaluator over the merged
state whose Answer is linked supported_by to findings from both
branches. Fully offline (§67) — the point is the state semantics, not a model.
A --conflict flag demonstrates the conflict-and-policy-resolve loop.
uv run python -m examples.forklab.main            # happy path
uv run python -m examples.forklab.main --mermaid  # merged provenance graph
uv run python -m examples.forklab.main --conflict # explicit MergeConflict + policy
The same pattern is the natural base for rewriting medic-lab: hypotheses
become real forks instead of tag-routed channels.
ledger — minimal recompute (reactive dependency graph)¶
What it shows: a tiny cost model (hours × rate → labor cost → tax/discount
→ total), built to make one point concretely, with numbers: dependencies are
declared on artifact types via Consume, not wired between nodes sharing one
blob of state — so editing one fact recomputes exactly what actually consumed
it, and nothing else. Artifact.version is the proof: a formula that never
consumed the edited fact is never even invoked for that edit, not
"invoked-and-decided-not-to-update." No LLM, fully deterministic (§67) — same
offline-proof spirit as forklab, but for reactive invalidation instead of
branch/merge.
fintech_audit — auditable, reproducible answer¶
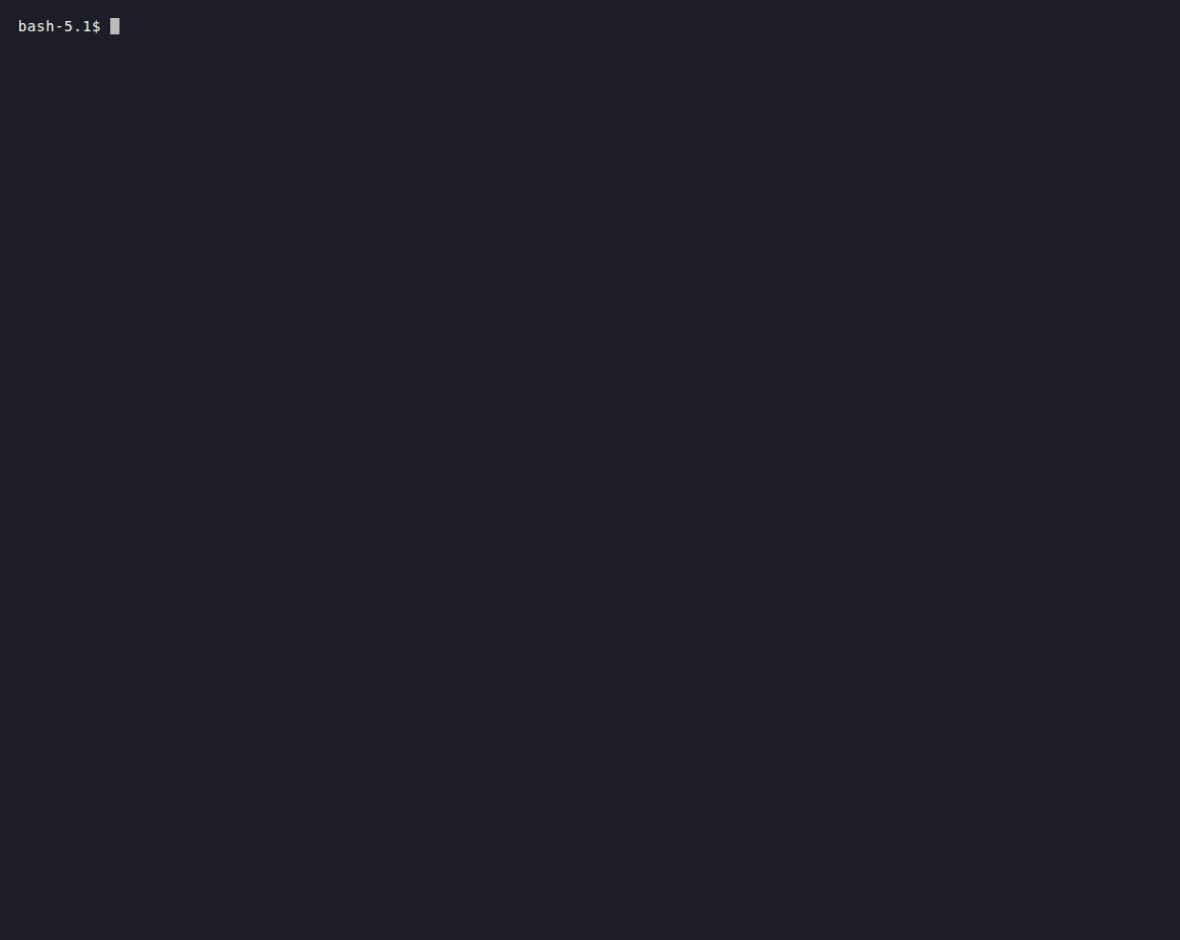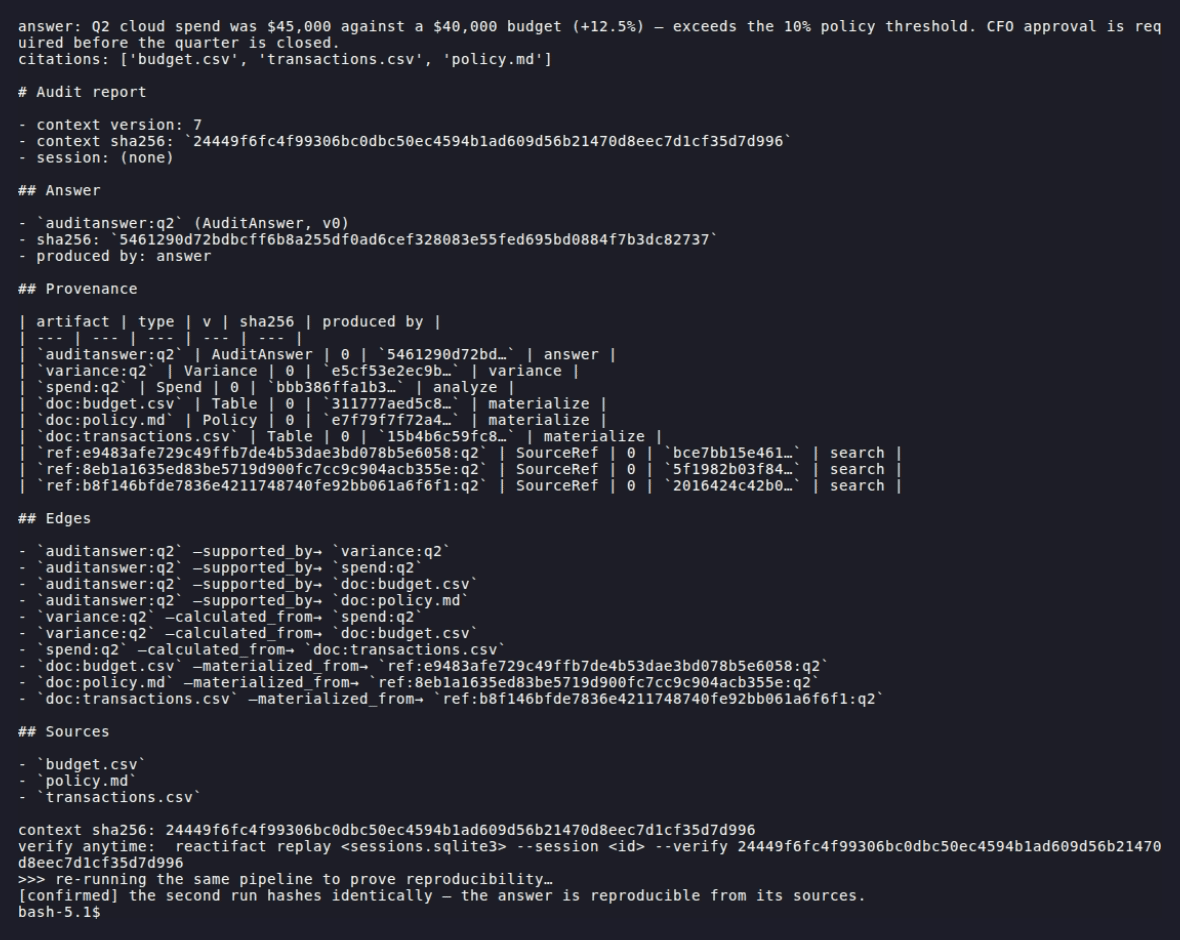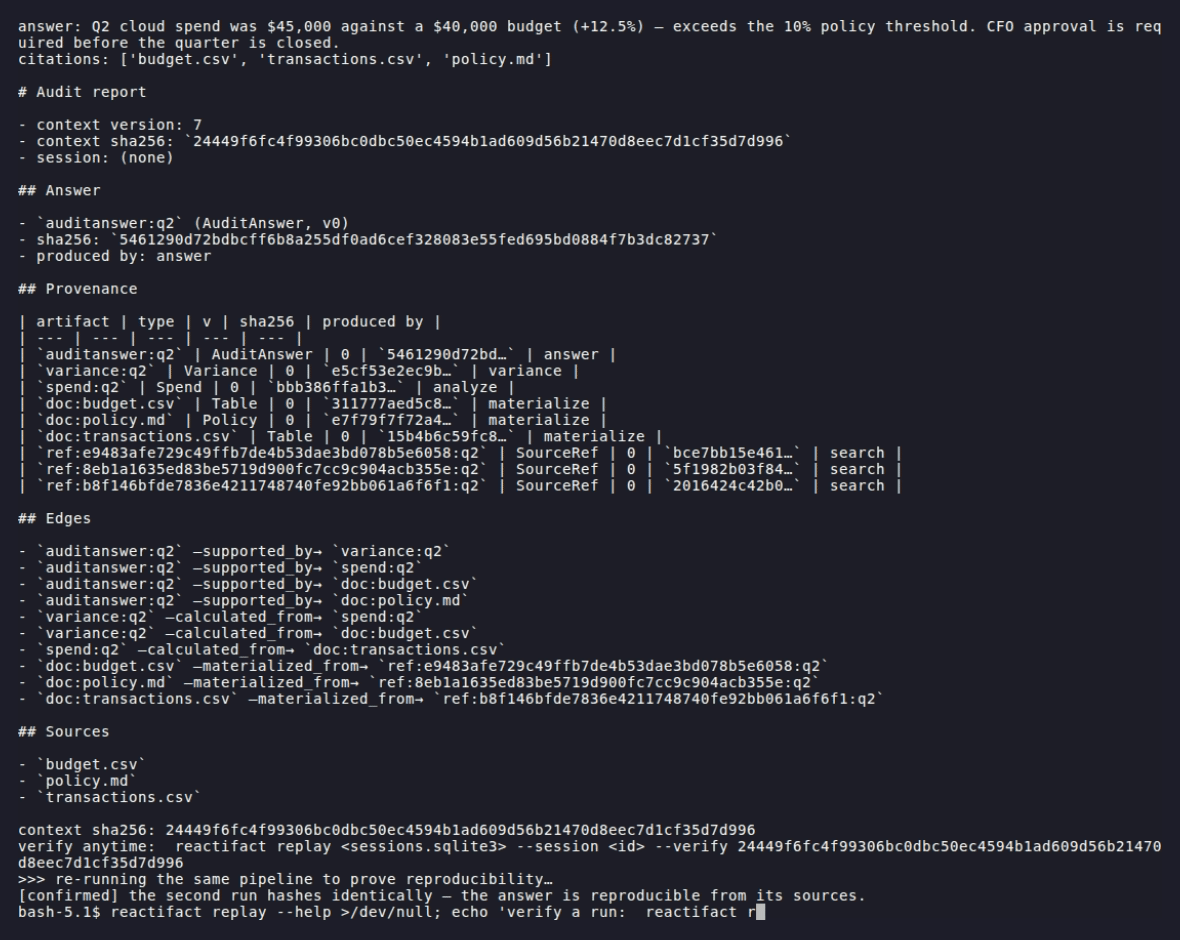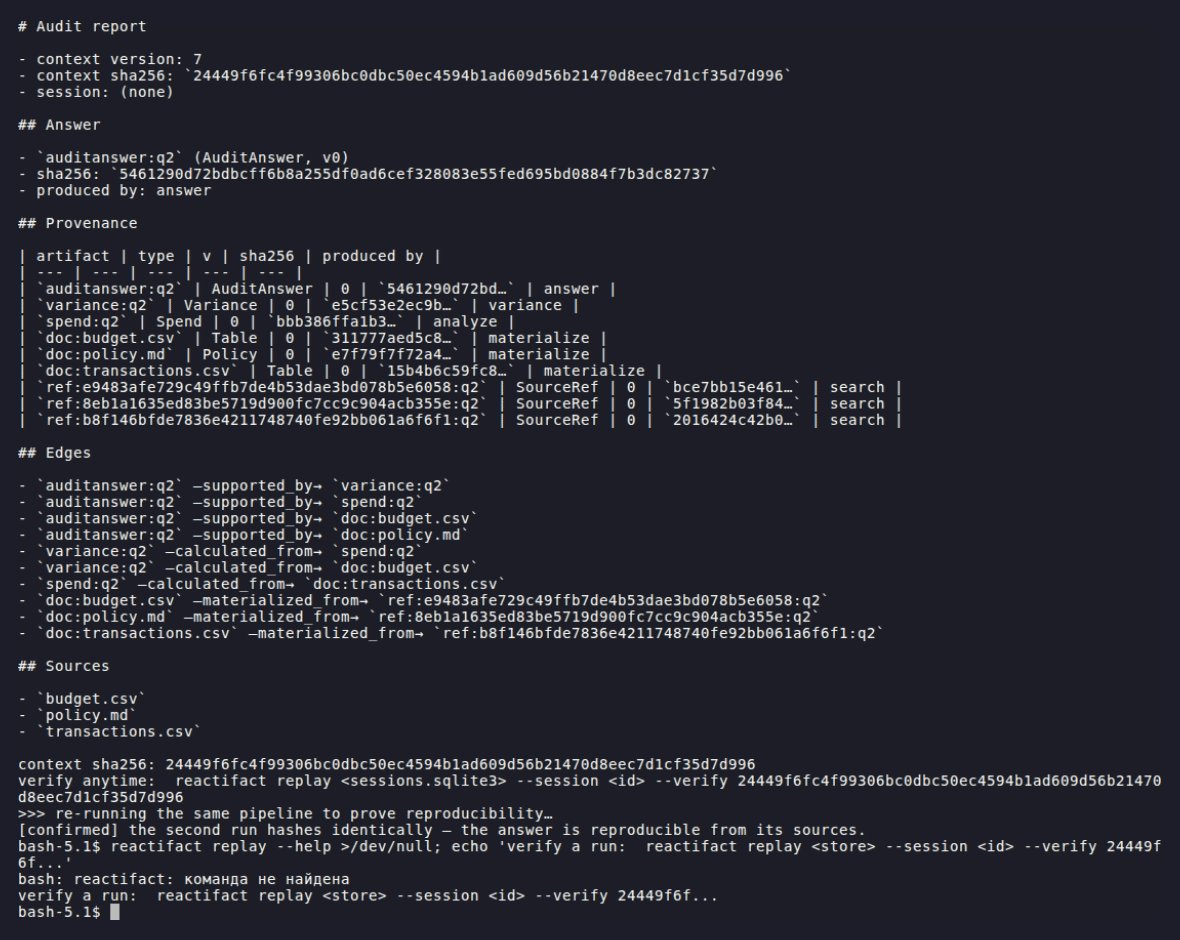
What it shows: a finance question ("what is the Q2 cloud spend variance,
and does policy require approval?") answered from a transactions CSV, a budget
CSV and a policy document. The audit story, end to end: the figures are computed
in plain Python (the model is never the source of truth, §67); every derived
artifact links to what it came from; reactifact.audit.build_report renders the
answer with a content hash per artifact and a context_sha256 for the run; and
re-running the pipeline hashes identically — the check
reactifact replay <store> --session <id> --verify <hash> runs against a saved
session. Offline, no key.
See also reactifact/audit.py (build_report,
context_hash, report_to_markdown) and Observability for
shipping such a run to a sink with redactor=.
support_copilot — grounded reply, or escalate, never hallucinate¶
What it shows: a support agent with two honest outcomes — the docs cover the
question → a grounded reply made of the matched document's own text, citing it
via supported_by provenance; nothing matches → the runtime escalates to a
human (effects.ask(...) → PendingQuestion), and the human's answer becomes
the reply. "I don't know" is a first-class state, not an invented answer. No
model required.
repo_agent — a coding agent behind an approval gate¶
What it shows: an LLM + tools agent where git_commit is
@tool(destructive=True) — the model may decide to call it, but the runtime
turns that into a PendingQuestion(kind="approve") and only runs the commit
after a human resume. Safe tools (read_file, run_tests) run freely. The
gate is a property of the Tool, not of the prompt, so it holds regardless of
what the model outputs. Offline (scripted provider, local tools).
adaptive — hybrid scheduling¶
What it shows: the adaptive planner (reactifact.scheduler) in action — hard
filter rules prune capabilities, a deterministic metric ranks the rest, an
optional LLM breaks ties, rank_limit caps the number of agents that actually
run; HITL-enabled agents are pinned, none starve.
uv run python -m examples.adaptive.main            # "money" → picked: b
uv run python -m examples.adaptive.main --tag x    # rule prunes b entirely
Canonical ports (offline-capable mini-demos)¶
Small, self-contained ports of the classic agent patterns — every one runs
uv run python -m examples.<name>.main and is mapped in the
port matrix. plan_execute, supervisor, and reflection
each also ship a main_recipe.py running the identical scenario on the
corresponding reactifact.recipes class (python -m examples.<name>.main_recipe)
— compare the two to see exactly what the recipe takes off your hands.
reflection— generate → critique → regenerate a draft until a guard passes.map_reduce— chunk a document, per-chunk produces, then aggregate (fan_out+combine).supervisor— a supervisor delegates specialist produces (HITL approvals).summarize— conversation memory summarization (short → long window).time_travel—Context.branch(), run two strategies in parallel, three-waymerge().plan_execute— planner drafts ordered steps, executor runs exactly one per generation gated on the previous step's result, finisher synthesizes the answer once every step has one; see patterns.
Running tests¶
.venv/bin/python -m pytest      # 543 tests (2 skipped without TEST_PG_DSN)
.venv/bin/mypy                  # strict typing across the repo
.venv/bin/ruff check            # lint
uv sync installs the dev+web groups from pyproject.toml; uv build ships
only the reactifact wheel (examples and docs are not packaged).